# Partition for the delete
> Partition big time-series tables for retention and maintenance, read pruning in real plans, dodge the pitfalls, and convert a live table without downtime.
---
LLMS index: [llms.txt](/en/llms.txt)
---
We deleted one month of events from the book's `events` table, 164,383 rows, with an ordinary `delete ... where created_at ...`. It wrote 32 MB of WAL, left 164,383 [dead tuples](/en/43-glossary/#dead-tuple) behind, and the vacuum that cleaned them up wrote another 12 MB. Then we removed the same month from a partitioned copy of the table by detaching and dropping one partition. That wrote under 150 KB.
**Figure 39-1.** Deleting a month is work\; dropping one is a file\. The delete left 164\,383 dead tuples and wrote 32 MB of WAL\, and the vacuum after it wrote another 12 MB\. Detaching and dropping the month\'s partition unlinks its files and wrote under 150 KB\.
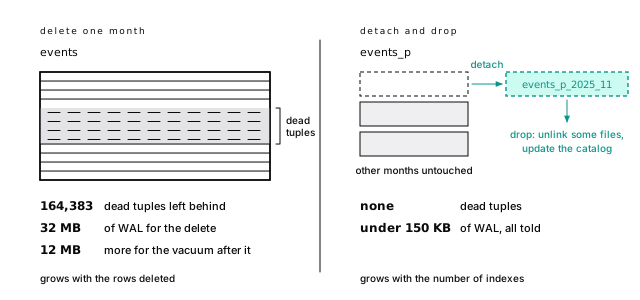
At two billion rows, that `delete` becomes the nightly job that runs for hours and floods the replicas. The drop stays the same size: unlink some files, update the catalog.
That's the honest pitch. Partitioning is a data lifecycle feature first. It isn't a general speedup, and for queries that don't carry the partition key it makes things slower.
## Every benefit comes from separate tables
A partitioned table is a parent that holds no rows. Every row lives in exactly one child, a **partition**, chosen by the value of the **partition key**. Each partition is an ordinary table with its own heap, indexes, visibility map, and autovacuum schedule. That separation buys four things:
- **Retention is a drop.** Removing old data is dropping a table: no dead tuples, almost no WAL, nothing for vacuum.
- **Maintenance works on pieces.** Autovacuum handles a 30 GB partition, not a 3 TB table. Old partitions freeze once, and later vacuums skip their pages. You can reindex or repack one at a time.
- **Hot indexes stay small.** The current month's indexes fit in memory even when the full history doesn't.
- **Pruning.** A query that filters on the key touches only the partitions that can match.
## Partitioning doesn't make lookups faster
A B-tree descent costs three or four pages at a million rows or a billion ([A B-tree is a shallow tree of pages](/en/17-btree/#a-b-tree-is-a-shallow-tree-of-pages)), so splitting a table doesn't make a well-indexed lookup faster. When the query doesn't name the key, splitting multiplies the lookups: a lookup by `id` read 7 pages on `events` and 39 on `events_p`, its monthly-partitioned copy, searching every partition's index. With 14 partitions that's small. With 1,000 it isn't ([Every partition a query can't prune costs planning time](#every-partition-a-query-cant-prune-costs-planning-time)).
For faster time-range reads there's a cheaper tool: a 24 KB BRIN index on `created_at` ([BRIN keeps one summary per range of pages](/en/18-more-indexes/#brin-keeps-one-summary-per-range-of-pages)) counted March's events in 3,251 pages; the partitioned table, pruned to March, in 2,988.
So partition for what only partitioning gives you: cheap retention, per-partition maintenance, or a table whose vacuum and index builds no longer fit your windows. Leave a table under tens of gigabytes alone unless it has a retention requirement, and wait until `pg_stat_statements` confirms your top queries carry the key.
> [!DETAILS]- Deep dive: The id lookup, one table against fourteen
>
> ```text
> Index Scan using events_pkey on events (actual rows=1.00 loops=1)
> Index Cond: (id = 1234567)
> Buffers: shared hit=3 read=4
> Planning:
> Buffers: shared hit=22 read=1
> ```
>
> ```text
> Append (actual rows=1.00 loops=1)
> Buffers: shared hit=31 read=8
> -> Index Scan using events_p_2025_10_pkey on ... (actual rows=0.00 ...)
> Index Cond: (id = 1234567)
> Buffers: shared hit=3
> ... (one scan per partition, 14 in all)
> Planning:
> Buffers: shared hit=202 read=4 dirtied=4
> ```
>
> Planning time went from 0.055 ms to 0.284 ms (in a fresh session; your numbers will differ slightly), because the planner had to consider every partition.
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('a lookup by id alone: one index scan per partition on events_p',
> > (select count(distinct r) from unnest(rels('select * from events_p where id = 1234567')) r) = :nparts);
> >
> > select lab.prove('a lookup by id: about 7 pages on events, several times that on events_p',
> > lab.buffers('select * from events where id = 1234567') <= 10
> > and lab.buffers('select * from events_p where id = 1234567') > 3 * lab.buffers('select * from events where id = 1234567'));
> >
> > select lab.prove('with BRIN, the unpartitioned month read is within 15% of the pruned partition read',
> > lab.buffers(:'q_mid') < 1.15 * lab.buffers(:'q_mid_p'));
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Range fits time; list and hash have narrow jobs
Declarative partitioning (`partition by`, PostgreSQL 10+, better in every release since) has three strategies:
| Strategy | Key | Good for |
|---|---|---|
| Range | a continuous value, usually time | events, logs, metrics, anything with retention |
| List | discrete values | regions, a few very large tenants |
| Hash | hash of the key, modulo N | splitting one huge hot table into equal pieces |
**Table 39-1.** Range fits time; list and hash have narrow jobs
This chapter's `events_p` is range-partitioned by month: fourteen partitions of about 3,000 pages each, against 35,173 for `events`. Its primary key is `(id, created_at)`, which is required ([why](#unique-constraints-must-include-the-key)).
List fits few, stable values, like EU data on its own storage. Hash gives no lifecycle benefit; it only splits one huge, busy table into medium ones for maintenance.
> [!DETAILS]- Deep dive: Building events_p, and what list and hash look like
>
> ```sql
> create table events_p (
> id bigint generated always as identity,
> account_id bigint not null,
> project_id bigint not null,
> user_id bigint,
> kind text not null,
> payload jsonb not null default '{}',
> created_at timestamptz not null default now(),
> primary key (id, created_at)
> ) partition by range (created_at);
> ```
>
> Range bounds include the lower end and exclude the upper, the same half-open interval you should use in queries. Generate the partitions; in psql, `\gexec` runs each result row as a statement:
>
> ```sql
> select format(
> 'create table events_p_%s partition of events_p '
> 'for values from (%L) to (%L)',
> to_char(m, 'YYYY_MM'), m, m + interval '1 month')
> from generate_series(date_trunc('month', timestamptz '2025-10-06'),
> date_trunc('month', timestamptz '2026-11-01'),
> interval '1 month') as m
> \gexec
> ```
>
> Then copy the data with `insert ... overriding system value select ... from events`, move the identity sequence past the copied ids with `setval`, and `vacuum analyze`. Counting rows by `tableoid::regclass` (the system column naming the table a row physically lives in) confirms the routing:
>
> ```text
> partition | count | pages
> ------------------+--------+-------
> events_p_2025_10 | 141830 | 2495
> events_p_2025_11 | 164383 | 2891
> ...
> events_p_2026_10 | 28034 | 493
> (13 rows)
> ```
>
> A fourteenth partition, November 2026, exists empty, ready before its rows arrive.
>
> A list partition rejects a row whose key matches nothing (`no partition of relation "audit_log" found for row`). A hash-partitioned `sessions_h` with `modulus 4` spread 400,000 rows into buckets of 100,504, 99,912, 99,884 and 99,700, and `where user_id = 42` scanned exactly one.
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('every row lands in exactly one partition, and the copy keeps all 2,000,000',
> > (select count(*) from events_p) = 2000000
> > and (select count(*) from only events_p) = 0);
> >
> > select lab.prove('a full month is about 3,000 pages; the unpartitioned events is about 35,000',
> > (select max(pg_relation_size(inhrelid)) / 8192 from pg_inherits
> > where inhparent = 'events_p'::regclass) between 2800 and 3100
> > and pg_relation_size('events') / 8192 between 34000 and 36500);
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Choose the key you delete by
The partition key should be what you retire data by, and ideally what most queries filter on. For events, logs, and metrics those are the same column, the timestamp, which is why they partition so well.
When they differ, retention usually wins. A SaaS app filters by `account_id`, but partitioning by account makes retention a row-by-row delete again. Partition by time and lead each partition's indexes with `account_id`; spreading tenants across machines is [sharding](/en/40-sharding/#basics-chapter-40)'s job.
Let retention pick the granularity, and aim for partitions of several gigabytes and counts in the tens to low hundreds. Monthly for ten years is 120 partitions. Daily is 3,650, and you'll feel it.
## The bounds are a free, coarse index
**Partition pruning** is skipping the partitions that can't hold matching rows. Counting March's events, with no index on `created_at`, read 2,988 pages on `events_p` against 35,173 on `events`: only March's partition even appears in the plan.
When the value isn't known at plan time (`now()`, a [generic plan](/en/43-glossary/#generic-plan)'s parameter), Postgres prunes as execution starts, and the plan says `Subplans Removed: 11`. Either way it needs the bare key: `date_trunc('day', created_at) = ...` scans all fourteen partitions, the half-open range scans one ([Keep the indexed column bare](/en/22-queries/#keep-the-indexed-column-bare)).
Without the key, even a cheap query pays at planning time: "account 42's latest 20 events" read partitions newest first and stopped at 23 pages, like the plain table, but planning touched 455 pages against 54.
> [!EXAMPLE]- Prove it · lab `38-partitioning`
>
> ```sql
> select lab.prove('one month on events_p: only that partition appears in the plan',
> (select count(distinct r) from unnest(rels(:'q_mid_p')) r) = 1);
>
> select lab.prove('one month reads about 3,000 pages on events_p and all ~35,000 on events',
> lab.buffers(:'q_mid_p') < 3100 and lab.buffers(:'q_mid') > 34000);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
> [!DETAILS]- Deep dive: Pruning in the plans: plan time, run time, and stopping early
>
> ```text
> Finalize Aggregate (actual rows=1.00 loops=1)
> Buffers: shared hit=149 read=2839
> ...
> -> Parallel Seq Scan on events_p_2026_03 events_p
> (actual rows=84931.50 loops=2)
> ```
>
> The other thirteen partitions never show up. With `where created_at >= now() - interval '7 days'` (PostgreSQL 11+ prunes at run time):
>
> ```text
> Aggregate (actual rows=1.00 loops=1)
> Buffers: shared hit=12 read=737
> -> Append (actual rows=38235.00 loops=1)
> Subplans Removed: 11
> -> Index Only Scan using events_p_2026_09_pkey on events_p_2026_09 ...
> -> Index Only Scan using events_p_2026_10_pkey on events_p_2026_10 ...
> -> Seq Scan on events_p_2026_11 events_p_3 (actual rows=0.00 loops=1)
> ```
>
> A generic prepared plan's `where created_at >= $1` shows the same `Subplans Removed: 11`. A partition marked `(never executed)` can be run-time pruning too, or, as in the next plan, a `Limit` that stopped before reaching it.
>
> Newest first, stopping early (PostgreSQL 12+ appends range partitions in order instead of merging them):
>
> ```text
> Limit (actual rows=20.00 loops=1)
> Buffers: shared hit=21 read=2
> -> Append (actual rows=20.00 loops=1)
> -> Index Scan Backward using events_p_2026_11_account_id_created_at_idx
> Buffers: shared hit=2
> -> Index Scan Backward using events_p_2026_10_account_id_created_at_idx
> Buffers: shared hit=19 read=2
> -> Index Scan Backward using events_p_2026_09_account_id_created_at_idx
> Index Searches: 0
> ... (the other 11 also never executed)
> Planning:
> Buffers: shared hit=431 read=24
> Planning Time: 1.251 ms
> ```
>
> Planning took about ten times as long as on the plain table (1.25 ms against 0.1 ms in a fresh session).
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('a filter on now() prunes when execution starts: Subplans Removed > 0',
> > (lab.plan($$ select count(*) from events_p where created_at >= now() - interval '7 days' $$)
> > @? '$.** ? (@."Subplans Removed" > 0)'));
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Partition-wise plans are for reports
Pruning works one table at a time. `enable_partitionwise_join` joins two identically partitioned tables partition by partition, and `enable_partitionwise_aggregate` groups per partition. Both are off by default because every per-partition hash or sort gets its own [`work_mem`](/en/43-glossary/#work_mem): a plan over 100 partitions can use 100 times your budget.
On a quarterly join of `events_p` to a `deliveries_p` partitioned by the same months, it cut 46.9 ms to 17.6. But stating the range on both sides, so each side prunes alone, was the simpler fix. Use the settings per session for reports, never for OLTP.
> [!DETAILS]- Deep dive: The join, before and after, and how aggregates split
>
> ```text
> GroupAggregate (actual rows=9398.00 loops=1)
> Buffers: shared hit=11878 read=181 written=83
> ...
> -> Parallel Hash Join (actual rows=4243.00 loops=3)
> -> Parallel Append (actual rows=168036.33 loops=3)
> -> Parallel Seq Scan on events_p_2026_07 e_1 ...
> ...
> -> Parallel Hash (actual rows=16741.00 loops=3)
> -> Parallel Append (actual rows=16741.00 loops=3)
> ... (all 14 deliveries partitions)
> Execution Time: 46.935 ms
> ```
>
> With `set enable_partitionwise_join = on`:
>
> ```text
> GroupAggregate (actual rows=9398.00 loops=1)
> Buffers: shared hit=51723 read=2
> ...
> -> Parallel Append (actual rows=4243.00 loops=3)
> -> Nested Loop (actual rows=1452.33 loops=3)
> -> Parallel Seq Scan on deliveries_p_2026_08 d_2 ...
> -> Index Scan using events_p_2026_08_pkey ...
> (actual rows=1.00 loops=4357)
> -> Nested Loop ... (July)
> -> Nested Loop ... (September)
> Execution Time: 17.637 ms
> ```
>
> More buffer hits (51,723 against 12,059), from thousands of cached index probes, but no hash build over eleven useless partitions. With `enable_partitionwise_aggregate`, grouping by the key aggregates whole inside each partition; by anything else, partially per partition then combined; by `date_trunc('month', created_at)`, neither.
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('default: the events side prunes to 3 months, the deliveries side scans every partition',
> > (select count(distinct r) filter (where r like 'events_p%') from unnest(rels(:'q_join')) r) = 3
> > and (select count(distinct r) filter (where r like 'deliveries_p%') from unnest(rels(:'q_join')) r) = :nparts);
> >
> > set enable_partitionwise_join = on;
> >
> > select lab.prove('partition-wise: only the 3 matching deliveries partitions are read',
> > (select count(distinct r) filter (where r like 'deliveries_p%') from unnest(rels(:'q_join')) r) = 3);
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Constraints must carry the partition key
### Unique constraints must include the key
Here's why `events_p`'s primary key is `(id, created_at)`:
```text
ERROR: unique constraint on partitioned table must include all partitioning columns
DETAIL: UNIQUE constraint on table "events_p" lacks column "created_at"
which is part of the partition key.
```
Postgres has no global index. An index on a partitioned table is one index per partition, so uniqueness is checked within one partition. If the unique key contains the partition key, equal keys land together; if not, duplicates can sit in different months unseen. (The same `id` went into May and September without complaint.) `on conflict` targets follow the same rule.
### References into a partitioned table must carry the key
Every unique key on `events_p` includes `created_at`, so `references events_p (id)` fails, and a referencing table must carry the partition key too, as `deliveries_p` does with `(event_id, event_created_at)`. Event tables partition well partly because few tables reference them.
> [!DANGER] Decide which guarantees you give up before you partition
>
> List every unique constraint and foreign key that touches the table before you start, and decide what replaces each: include the key, keep a small unpartitioned table for the unique value, or don't partition.
Indexes have their own catch: `create index concurrently` isn't supported on a partitioned parent. Create the index `on only` the parent, build each partition's concurrently, and attach each; the parent index turns valid after the last.
> [!DETAILS]- Deep dive: The constraint errors, and building an index partition by partition
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('a unique index on id alone is rejected: it lacks the partition key',
> > lab.try('create unique index on events_p (id)')
> > = '0A000: unique constraint on partitioned table must include all partitioning columns');
> >
> > select lab.prove('a foreign key to events_p (id) alone is rejected (42830)',
> > lab.try($$ create table event_comments (
> > id bigint generated always as identity primary key,
> > event_id bigint not null references events_p (id),
> > body text not null) $$)
> > = '42830: there is no unique constraint matching given keys for referenced table "events_p"');
> >
> > select lab.prove('the same id can exist twice, in different partitions',
> > (select count(*) = 2 and count(distinct tableoid) = 2 from events_p where id = 1234567));
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
>
> The duplicate needs something to supply ids explicitly (imports, `overriding system value`); an identity column hands out unique values on its own.
>
> The index build, generated per partition:
>
> ```sql
> create index events_p_kind_idx on only events_p (kind); -- indisvalid = f
>
> select format('create index concurrently %I on %s (kind)',
> c.relname || '_kind_idx', c.oid::regclass),
> format('alter index events_p_kind_idx attach partition %I',
> c.relname || '_kind_idx')
> from pg_inherits i join pg_class c on c.oid = i.inhrelid
> where i.inhparent = 'events_p'::regclass
> order by c.relname
> \gexec
> ```
>
> `create index concurrently` can't run inside a transaction block, so run the statements one at a time (psql's `\gexec` does, outside `begin`). If one build fails it leaves an invalid index on that partition; drop it and build again ([When a concurrent build fails](/en/26-migrations/#basics-26-when-a-concurrent-build-fails)).
## Avoid the default partition
A default partition catches rows that match no other. It looks like a safety net. It's closer to a trap: creating a partition must scan it under lock and fails if a stray row for that range is there, it blocks `detach ... concurrently`, and with a foreign key pointing at the table you can't drop it directly.
Make sure future partitions always exist instead, and treat a "no partition found" error as the alarm it should be.
> [!DETAILS]- Deep dive: The three errors a default partition earns you
>
> ```text
> ERROR: updated partition constraint for default partition "events_p_default"
> would be violated by some row
> ```
>
> ```text
> ERROR: cannot detach partitions concurrently when a default partition exists
> ```
>
> ```text
> ERROR: cannot drop table events_p_default because other objects depend on it
> DETAIL: constraint deliveries_p_event_id_event_created_at_fkey on table
> deliveries_p depends on table events_p_default
> ```
>
> (We emptied it, then `detach partition events_p_default` followed by `drop table` worked.)
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('with a stray row in the default, creating its month fails (23514)',
> > lab.try(format('create table events_p_future partition of events_p for values from (%L) to (%L)',
> > :'last_month'::timestamptz + interval '2 months',
> > :'last_month'::timestamptz + interval '3 months'))
> > like '23514: updated partition constraint for default partition "events_p_default" would be violated%');
> >
> > select lab.prove('a default partition blocks DETACH ... CONCURRENTLY',
> > lab.try(format('select dblink_exec(%L, %L)', 'dbname=' || current_database(),
> > format('alter table events_p detach partition %I concurrently',
> > 'events_p_' || to_char(:'first_month'::timestamptz, 'YYYY_MM'))))
> > = '55000: cannot detach partitions concurrently when a default partition exists');
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Retention: detach, then drop
This is the payoff. Deleting November 2025 (164,383 rows) two ways:
| | `delete` + vacuum | detach + drop |
|---|---|---|
| WAL written | 32.5 MB + 12.5 MB | about 140 KB |
| WAL records | 175,000+ | 226 |
| Dead tuples for vacuum | 164,383 | none |
| Index cleanup | every index, every row | none |
| Grows with | rows deleted | number of indexes |
**Table 39-2.** Retention: detach, then drop
The `delete` took under 100 ms, on small, cached data. Its cost grows with the rows, and so does the WAL every replica replays. The drop's doesn't. Both finished in well under a second here; only one will at a billion rows.
```sql
alter table events_p detach partition events_p_2025_11 concurrently;
drop table events_p_2025_11;
```
> [!DETAILS]- Deep dive: Where the numbers in that table came from
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.wal_bytes(format($$ delete from events where created_at >= %L and created_at < %L $$,
> > :'old_month'::timestamptz, :'old_month'::timestamptz + interval '1 month')) as delete_wal \gset
> > vacuum events;
> >
> > alter table deliveries_p detach partition :old_deliveries concurrently;
> > drop table :old_deliveries;
> > alter table events_p detach partition :old_events concurrently;
> > drop table :old_events;
> >
> > -- vacuum_wal and drop_wal come from pg_stat_statements
> > select lab.prove('deleting a month writes about 32 MB of WAL',
> > :delete_wal between 25e6 and 40e6);
> > select lab.prove('detach + drop writes over 100 times less WAL than delete + vacuum',
> > :drop_wal > 0 and (:delete_wal + :vacuum_wal) > 100 * :drop_wal);
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
>
> The `delete` under `explain (analyze, wal)`:
>
> ```text
> Delete on events (actual rows=0.00 loops=1)
> Buffers: shared hit=169243 read=5223 dirtied=2893
> WAL: records=164383 fpi=2893 bytes=32465375 buffers full=3503
> Execution Time: 85.682 ms
> ```
>
> The vacuum it left behind:
>
> ```text
> tuples: 164383 removed, 1835626 remain, 0 are dead but not yet removable
> WAL usage: 11670 records, 2098 full page images, 12504570 bytes, 181 buffers full
> ```
>
> Detach and drop, from `pg_stat_statements`: 135 records and 103,569 bytes, then 91 records and 36,971 bytes. Most of those bytes are full-page images, so the total moves with checkpoint timing: between 80 and 150 KB across our runs.
### Detach concurrently, or everything queues behind you
A plain `detach` takes an `ACCESS EXCLUSIVE` lock on the parent and queues everything behind it ([the lock queue](/en/25-concurrency/#a-waiting-lock-blocks-everyone-behind-it)). `detach partition ... concurrently` (PostgreSQL 14+) doesn't block queries. It can't run in a transaction block, and if interrupted it leaves the partition "detach pending" until `detach partition ... finalize`.
### Foreign keys set the order
With `deliveries_p` referencing `events_p`, detaching the events partition first fails with a foreign key violation. Retire the referencing partition first.
> [!TIP] A retention job that won't page you
>
> Daily, in order: create missing future partitions, finalize pending detaches, detach expired partitions concurrently (children first), archive if needed, drop, `analyze` the parent. Set `lock_timeout` so it gives up instead of queueing, and let the next run retry.
> [!DETAILS]- Deep dive: The foreign key that set the order
>
> ```text
> ERROR: removing partition "events_p_2025_12" violates foreign key constraint
> "deliveries_p_event_id_event_created_at_fkey_3"
> DETAIL: Key (event_id, event_created_at)=(306216, 2025-12-01 00:00:38.330131+00)
> is still referenced from table "deliveries_p".
> ```
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > select lab.prove('foreign keys set the order: the events partition can''t go before its deliveries (23503)',
> > lab.try(format('alter table events_p detach partition %I', :'old_events')) like '23503: removing partition%violates foreign key constraint%');
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Create partitions before you need them
Retention removes partitions at one end; something has to add them at the other. A missing partition doesn't degrade gracefully: every insert for that range fails. Keep several future partitions ready, created by a scheduled job, and alert when the furthest-ahead one is less than a few weeks out. The `\gexec` generator is most of that job. If you'd rather not own it, `pg_partman` is the extension most teams use ([pg_cron and pg_partman keep time on your side](/en/16-extensions/#pg_cron-and-pg_partman-keep-time-on-your-side)); read its defaults for your version, because they matter.
> [!DETAILS]- Deep dive: What pg_partman does, and the default it creates
>
> - Version 5 manages only native declarative partitioning; the older trigger-based method was removed.
> - `create_parent()` registers an existing partitioned table with a control column and an interval, and creates partitions ahead of time (`p_premake` defaults to 4).
> - `run_maintenance()` (or `run_maintenance_proc()`, which commits after each partition set) creates new partitions and applies retention. Run it from its background worker or a scheduler like `pg_cron`.
> - Retention lives in its `part_config` table: `retention` sets the age, and `retention_keep_table` (default true) detaches old partitions and keeps them rather than dropping them.
> - `create_parent()` creates a default partition unless you pass `p_default_table := false`. Given the problems above, consider turning it off, or at least monitor it for rows.
## Convert a live table without downtime
You can't `alter table ... partition by`. Instead, make the whole existing table the first partition, covering all of history, and let new partitions take the future. The trick is a `check` constraint that proves every row fits, so `attach partition` skips its validation scan:
1. **Online:** build a unique index on `(id, created_at)` concurrently, and add `check (created_at < '2026-11-01')` as `not valid`, then `validate` it without blocking writes ([the two-step move](/en/26-migrations/#add-a-check-not-valid-then-validate-it)).
2. **One short transaction, with `lock_timeout`:** rename the old table, make that index its primary key, move the identity column to a new partitioned parent, attach the old table up to the bound, create the next partitions, and `setval` the parent's sequence past the old ids. A partition can't keep its own identity, so skipping that step fails the attach.
On a 1.8 million row copy the transaction took about 20 ms. Without the constraint, the attach scanned every row under its lock: minutes or hours on a terabyte. (Filling new partitions in bulk: [Freeze the partition, attach it built, analyze the parent](/en/27-loading/#freeze-the-partition-attach-it-built-analyze-the-parent).)
> [!DETAILS]- Deep dive: The conversion, statement by statement
>
> ```sql
> create unique index concurrently events_copy_id_created_at_key
> on events_copy (id, created_at);
>
> alter table events_copy add constraint events_copy_old_range
> check (created_at < '2026-11-01') not valid;
> alter table events_copy validate constraint events_copy_old_range;
> ```
>
> Our first attach failed twice, with `The new partition may not contain an identity column.` and then `multiple primary keys for table "events_copy_old" are not allowed`. The old primary key on `(id)` has to go, the step 1 index becomes the new one (which `attach` adopts instead of building an index under lock), and the identity moves to the parent:
>
> ```sql
> begin;
> set local lock_timeout = '2s';
>
> alter table events_copy rename to events_copy_old;
> alter table events_copy_old drop constraint events_copy_pkey;
> alter table events_copy_old
> add constraint events_copy_old_pkey
> primary key using index events_copy_id_created_at_key;
> alter table events_copy_old alter column id drop identity;
>
> create table events_copy (
> id bigint generated always as identity,
> account_id bigint not null,
> project_id bigint not null,
> user_id bigint,
> kind text not null,
> payload jsonb not null default '{}',
> created_at timestamptz not null default now(),
> primary key (id, created_at)
> ) partition by range (created_at);
>
> alter table events_copy attach partition events_copy_old
> for values from (minvalue) to ('2026-11-01');
>
> create table events_copy_2026_11 partition of events_copy
> for values from ('2026-11-01') to ('2026-12-01');
> create table events_copy_2026_12 partition of events_copy
> for values from ('2026-12-01') to ('2027-01-01');
>
> select setval(pg_get_serial_sequence('events_copy', 'id'),
> (select max(id) from events_copy_old));
> commit;
> ```
>
> With `client_min_messages = debug1`, the attach says `partition constraint for table "events_copy_old" is implied by existing constraints`, in 0.468 ms. Afterwards an insert of one row for now and one for 2026-11-15 got ids 2000001 and 2000002, in `events_copy_old` and `events_copy_2026_11`.
>
> The old partition holds all of history, and retention on it stays a `delete` until its range expires (or you split months out of it in the background). Before trying this for real, check foreign keys that reference the old table, triggers and grants (they don't move by themselves), and code that names the sequence.
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > -- scan_nocheck / scan_check: seq scans of the old table counted (in
> > -- pg_stat_xact_user_tables) across the attach, without and with the constraint
> > select lab.prove('without the check constraint, attach scans the whole table',
> > :scan_nocheck = 1);
> > select lab.prove('with a validated check constraint, attach skips the scan',
> > :scan_check = 0);
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
## Partitioning costs most when queries can't prune
### Every partition a query can't prune costs planning time
A query that prunes barely notices how many partitions there are. One that can't pays for each, in planning time, memory, and locks. We planned a query with the key and one without (`where account_id = 42`) on 12 to 3,000 daily partitions:
| Partitions | With key, warm | Without key, warm | Without key, cold | Planner memory, without key |
|---|---|---|---|---|
| 12 | 0.02 ms | 0.05 ms | 0.9 ms | 124 KB |
| 365 | 0.13 ms | 4.2 ms | 19 ms | 3.1 MB |
| 1,000 | 0.13 ms | 15.0 ms | 55 ms | 8.4 MB |
| 3,000 | 0.14 ms | 52.0 ms | 170 ms | 27 MB |
**Table 39-3.** Every partition a query can't prune costs planning time
With the key, the count barely matters. Without it, planning takes 52 ms, and the first query on every new connection about three times that. Unpruned queries also lock every partition and index, spilling into the shared lock table until it can run out with "out of shared memory". Keep counts in the tens to low hundreds, and make the hot queries prune.
> [!DETAILS]- Deep dive: How we measured planning, and the locks it takes
>
> Warm numbers are medians of 15 runs in one session; cold is the median of five first plans, each in a new session. Each table had a primary key and an index on `account_id`. Planner memory is from `explain (memory)`, PostgreSQL 17+. The lab re-runs the first three rows.
>
> Locks held by `select count(*) from pt_N where account_id = 42` inside a transaction:
>
> | Partitions | Fast-path locks | Locks in the shared lock table |
> |---|---|---|
> | 12 | 40 | 0 |
> | 365 | 64 | 1,035 |
> | 1,000 | 64 | 2,940 |
> | 3,000 | 64 | 8,940 |
>
>
>
> **Table 39-4.** Every partition a query can't prune costs planning time
>
> Each backend has a few fast-path lock slots that avoid shared memory. In PostgreSQL 18 their number scales with `max_locks_per_transaction` (64 here); earlier versions had a fixed 16. The rest go into the shared lock table (`LWLock LockManager` waits under concurrency), sized at roughly `max_locks_per_transaction` times the number of connections.
>
> > [!EXAMPLE]- Prove it · lab `38-partitioning`
> >
> > ```sql
> > -- planning: median planning time of 15 runs per table, with and without the key
> > select lab.prove('without the key, planning grows with the partition count (1,000 is over 20 times 12)',
> > (select without_key from planning where n = 1000) > 20 * (select without_key from planning where n = 12)
> > and (select without_key from planning where n = 365) > 5 * (select without_key from planning where n = 12));
> >
> > select lab.prove('with the key, pruning keeps 1,000 partitions planning over 20 times faster than without it',
> > (select with_key * 20 < without_key from planning where n = 1000));
> > ```
> >
> > [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/38-partitioning.sql)
### Four smaller traps catch partitioned tables
- **Lookups by id alone** search every partition. Put the time in the URL, or use an id that encodes it ([UUIDv7](/en/13-keys/#uuidv7-is-the-default-and-it-reveals-creation-time) does).
- **The parent is never analyzed** by autovacuum. Analyze it from the retention job.
- **Updates that change the key** move the row: a delete plus an insert, never [HOT](/en/07-hot/#basics-chapter-7). Pick a key that doesn't change.
- **Partitioning too small.** A 5 GB table in 365 daily partitions gets all the overhead and none of the benefit.
## The short version
- Partition for lifecycle. Deleting a month cost 45 MB of WAL and 164,383 dead tuples; dropping its partition, under 150 KB.
- It's not an OLTP speedup: queries without the key search every partition, and BRIN gives most of the time-range benefit.
- Partition by the key you delete by (usually time); keep counts in the tens to low hundreds.
- Compare the bare key with a half-open range, and check pruning in `EXPLAIN`.
- Every unique key must include the partition key, and references must carry it.
- Retire with `detach ... concurrently` and `drop`, children first, with `lock_timeout`. Avoid default partitions.
- Create future partitions ahead of time, and alert when they run short.
- Convert a live table by attaching it whole, with a validated `check` constraint so the attach skips its scan.
## Further reading
- [Table partitioning](https://www.postgresql.org/docs/18/ddl-partitioning.html), PostgreSQL documentation. The reference for declarative partitioning, its limitations, and the best-practices section on partition counts.
- [ALTER TABLE](https://www.postgresql.org/docs/18/sql-altertable.html), PostgreSQL documentation. The exact locks for `ATTACH` and `DETACH PARTITION`, the `check` constraint that skips the scan, and the rules for `CONCURRENTLY`.
- [Query planning configuration](https://www.postgresql.org/docs/18/runtime-config-query.html), PostgreSQL documentation. What `enable_partitionwise_join` and `enable_partitionwise_aggregate` do and why they cost memory.
- [CREATE TABLE](https://www.postgresql.org/docs/18/sql-createtable.html), PostgreSQL documentation. The `partition by` and `partition of` syntax, including list, hash and default partitions.
- [pg_partman](https://github.com/pgpartman/pg_partman), GitHub. The common extension for creating partitions ahead of time and applying retention; read the docs for your version's defaults.