# Know the nouns first
> A primer on the SQL and PostgreSQL basics every later chapter assumes, from tables, queries, updates, joins, and indexes to the server, its processes, schemas, roles, transactions, the catalog, settings, and the files underneath.
---
LLMS index: [llms.txt](/en/llms.txt)
---
This book argues about pages, plans, and locks. Those arguments assume some SQL and a handful of Postgres nouns. If you've written `select`, `insert`, and `update` against Postgres and know what a schema is, skim the headings below and move on; you lose nothing. If you haven't, this primer is your crash course: the least you need to follow every chapter after it.
Fair warning about what comes next: the rest of the book assumes everything here and goes deep fast, down to the bytes on disk, because that's where the answers to "why is this slow?" live. Every claim in this chapter runs against the lab server, like the rest of the book, so even the basics come with proof.
## A table is rows that share the same columns
Postgres keeps your data in **tables**. A table has named, typed **columns**, and every **row** holds one value for each column, or **NULL**, which means "no value" (not zero, and not an empty string). Here's the book's biggest table, `events`:
```sql
create table events (
id bigint generated always as identity primary key,
account_id bigint not null references accounts (id),
project_id bigint not null references projects (id),
user_id bigint references users (id),
kind text not null,
payload jsonb not null default '{}',
created_at timestamptz not null default now()
);
```
Read it line by line and you've met most of what a schema says. `bigint` is a large integer, `text` is a string of any length, `jsonb` is a JSON document, and `timestamptz` is a moment in time. `not null` forbids NULL, and `default` fills in a value when you don't give one. The `id` is the **primary key**: a value no other row shares, which Postgres numbers for you, so any row can be found by it. Each `references` line is a **foreign key**: `account_id` must name a row that exists in `accounts`.
`events` holds two million rows, every one with the same seven columns. A table is the shape; the rows are the data.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('events has 2,000,000 rows, every one with the same seven columns',
> (select count(*) from events) = 2000000
> and (select count(*) from information_schema.columns
> where table_schema = 'public' and table_name = 'events') = 7);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## SELECT asks, and changes nothing
You read with `select`. Name the columns you want, the table they come `from`, and a `where` clause that keeps only the rows you care about; `order by` sorts them and `limit` stops early:
```sql
select id, kind, created_at
from events
where project_id = 4242
order by created_at desc
limit 3;
```
Two more words cover most reports. `count(*)` counts rows, and `group by` counts them per value:
```sql
select kind, count(*)
from events
group by kind;
```
A `select` never changes anything. It doesn't even take a transaction ID (XID), the number Postgres stamps on every change. That doesn't make it free. The whole book is about how many pages a `select` has to read to answer you.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('a select takes no transaction id: reading writes nothing',
> pg_current_xact_id_if_assigned() is null);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## INSERT adds a row, and in Postgres so does UPDATE
Three statements change data. `insert` adds rows, `update` changes them, and `delete` removes them. Here they are on `notes`, a scratch table with an `id` and a `body`:
```sql
insert into notes (id, body) values (1, 'first draft');
update notes set body = 'second draft' where id = 1;
delete from notes where id = 1;
```
Always give `update` and `delete` a `where`. Without one, they apply to every row in the table, and Postgres won't ask whether you meant it.
Here's the first thing that makes Postgres Postgres. An `update` doesn't change the row where it sits. It writes a complete new copy of the row, on the same page if there's room, and marks the old copy as replaced. A `delete` marks the row dead and leaves it in place. Both old copies stay on the page until **vacuum**, a background cleanup, clears them. On a one-row table, one `update` left two copies on the page, and after the `delete` there were still two copies of a row the table no longer has.
That one fact explains why tables grow, why vacuum exists, and why a busy table can be twice the size of its data. The book calls it [Updates are inserts](/en/06-mvcc/#basics-chapter-6), and it comes back in nearly every chapter.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('an update gives the row a new address',
> (select ctid::text from notes where id = 1) <> :'ctid_before');
> select lab.prove('and leaves the old version on the page: one row, two copies',
> (select count(*) from notes) = 1
> and (select count(*) from heap_page_items(get_raw_page('notes', 0))) = 2);
> select lab.prove('a delete leaves the row on the page too, marked dead, for vacuum to clear',
> (select count(*) from notes) = 0
> and (select count(*) from heap_page_items(get_raw_page('notes', 0))) = 2);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## JOIN puts the tables back together
A good schema stores each fact once: a user's email lives in `users`, an account's plan in `accounts`. A **join** brings them back together by matching rows across tables, almost always on a foreign key:
```sql
select u.email, a.plan
from users u
join accounts a on a.id = u.account_id
where u.id = 295;
```
The `u` and `a` are short names for the tables, and `on` says which rows match: here, the account whose `id` is the user's `account_id`. User 295 belongs to account 296. A plain `join` keeps only rows that match on both sides; `left join` keeps every row on the left, with NULLs where nothing matched.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('a join follows account_id from a user to its account: user 295 is in account 296',
> (select a.id from users u join accounts a on a.id = u.account_id where u.id = 295) = 296);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## An index makes one read cheap and every write dearer
Ask for one user by email, and without help Postgres reads the whole `users` table to find it: 1,126 pages for one row. (The `unique (account_id, email)` constraint has an index, but it's sorted by account first, so finding an email through it means searching it once per account, and the planner reads the table instead.) An **index** is a separate, sorted structure that points at rows, like the index at the back of a book. Build one on `email` and the same lookup reads 4 pages:
```sql
create index users_email_idx on users (email);
```
Indexes aren't free. Every `insert`, and every `update` that changes an indexed column, has to update each index too. So index the columns your queries actually search on, not every column you have. [The B-tree does the heavy lifting](/en/17-btree/#basics-chapter-17) shows how an index finds a row in a handful of pages.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('finding one user by email reads hundreds of pages without an index and a handful with one',
> :before_index > 300 and :after_index < 10);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
That's enough SQL to follow the book. The rest of this chapter is the server underneath it.
## One server runs many databases, and they don't share tables
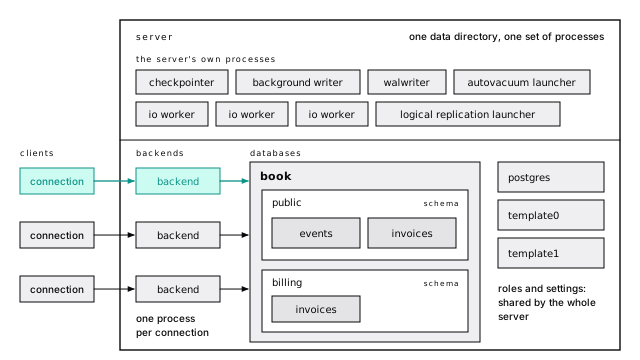
A Postgres **server** is one data directory and the processes running on it. The documentation calls it a **cluster**, which has nothing to do with several machines; it's one server. It holds many **databases**. The lab server has four:
```text
datname | datistemplate
-----------+---------------
book | t
postgres | f
template0 | t
template1 | t
```
A connection picks one database and sees only that one. Try to read another and Postgres refuses:
```text
ERROR: cross-database references are not implemented: "book.public.events"
```
That's a design decision, not a missing feature: each database has its own tables, its own catalog, and its own extensions. Roles, tablespaces, and the server's configuration file are the exceptions, shared by the whole server. If two parts of your app need to join their data, they belong in one database, in two schemas.
`create database` copies `template1` unless you name another template; `template0` is a pristine spare. The lab marks `book` as a template too, which is why `create database scratch template book` is far cheaper than loading the data again.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('the server holds several databases, book among them, and book is a template',
> (select count(*) from pg_database) >= 4
> and (select datistemplate from pg_database where datname = 'book'));
> select lab.prove('a query can''t reach into another database',
> lab.try($$ select count(*) from book.public.events $$)
> like '0A000: cross-database references are not implemented%');
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## Every connection is its own process
When your app connects, the server starts a new operating-system process to serve it, a **backend**, and that process lives until the connection closes. Ten connections are ten processes, each with its own memory. That one fact explains why connections are expensive, why `max_connections` is a ceiling and not a capacity, and why every production app ends up behind a pooler ([Connections aren't free](/en/28-connections/#basics-chapter-28)).
The server runs its own processes too. On the lab server, beside the one client:
```text
backend_type | count
------------------------------+-------
autovacuum launcher | 1
background writer | 1
checkpointer | 1
client backend | 1
io worker | 3
logical replication launcher | 1
walwriter | 1
```
Most of the book is about what those do: the WAL writer flushes the [write-ahead log](/en/08-wal/#basics-chapter-8) in the background, the checkpointer and background writer write changed pages back to their files, the autovacuum launcher starts [vacuum](/en/10-vacuum/#basics-chapter-10) workers, and the io workers (PostgreSQL 18+) do reads on the backends' behalf.
**Figure 2-1.** One server\, many databases\, a process per connection\. Each connection gets its own backend process\, which works in one database\; inside it\, schemas hold the tables\. Beside the backends\, the server runs its own processes\, and roles and settings belong to the whole server\.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('a second connection is served by a different server process',
> (select pid from dblink('other', 'select pg_backend_pid()') as t(pid int)) <> pg_backend_pid());
> select lab.prove('the server runs its own processes too: a checkpointer, a WAL writer, an autovacuum launcher',
> (select count(distinct backend_type) = 3 from pg_stat_activity
> where backend_type in ('checkpointer', 'walwriter', 'autovacuum launcher')));
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## Schemas are folders, and search_path picks the one you meant
Inside a database, tables live in **schemas**: named folders, one level deep. Every new database has one called `public`, and if you've never created another, everything you own is in it. `public.invoices` and `billing.invoices` are two different tables.
When you write a bare `invoices`, Postgres looks through the schemas named in `search_path`, in order, and uses the first match. Put `billing` first and the same query reads a different table. That's convenient for organizing a big schema. It's also how a function can end up calling something you didn't write, which is why [the security chapter](/en/33-security/#basics-chapter-33) pins `search_path` on every function that runs with elevated rights.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('with the default search_path, invoices means public.invoices',
> (select note from invoices) = 'public');
> set search_path = billing, public;
> select lab.prove('put billing first and the same query reads billing.invoices',
> (select note from invoices) = 'billing');
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## A role is a user, a group, or both
Postgres has one kind of principal, the **role**. A role with the `LOGIN` attribute is what you'd call a user; a role without it is a group; and any role can be a member of another and inherit its privileges. Every table has an **owner** role, which can do anything to it, and every other role gets only what it's granted.
The habit to build now: your application should connect as a role that owns nothing and isn't a superuser, so a bug in the app can't drop a table. [Trust no tenant](/en/33-security/#basics-chapter-33) shows the setup.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('a role with LOGIN is a user; one without is a group, and membership links them',
> (select rolcanlogin from pg_roles where rolname = 'ana')
> and not (select rolcanlogin from pg_roles where rolname = 'reporting')
> and pg_has_role('ana', 'reporting', 'member'));
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## Every statement runs in a transaction
Postgres never runs a statement outside a transaction. Send one `update` on its own and Postgres wraps it in a transaction that commits when the statement finishes; that's **autocommit**, and it's what your driver does unless you say `begin`. Two statements sent that way are two transactions, each paying for its own commit.
Inside `begin` and `commit`, everything lands together or not at all, and in Postgres "everything" includes schema changes. A `create table` rolled back is gone, so a migration that runs in one transaction and fails leaves nothing half-done ([ACID, honestly](/en/09-acid/#basics-chapter-9)). It also means a long transaction holds everything it touched, locks included, until it ends. You'll meet that open transaction again and again in this book.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('a rolled-back transaction takes its create table with it',
> to_regclass('scratch_t') is null);
> select lab.prove('two statements outside begin run as two transactions, with two transaction ids',
> :xid1 < :xid2);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## The server describes itself in tables
Everything Postgres knows about your schema lives in ordinary tables you can query, the **system catalog**. `pg_class` lists every table and index, `pg_attribute` their columns, `pg_roles` the roles, `pg_settings` every setting. The `pg_stat_` views count what the server has been doing. psql's backslash commands, like `\d events`, are queries over these tables.
The catalog already counts pages for you:
```text
relname | relkind | relpages | reltuples
---------+---------+----------+-----------
events | r | 35173 | 1999995
```
That's the planner's picture of `events`: 35,173 pages and about two million rows, updated by `vacuum` and `analyze`. That page count is the number this whole book keeps returning to.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('pg_class already knows events is 35,173 pages and about 2 million rows',
> (select relpages = 35173 and reltuples between 1990000 and 2010000 from pg_class where relname = 'events'));
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## A setting has a value, a source, and a scope
Postgres has a few hundred **settings**, like `work_mem`, the memory one sort may use (4 MB by default). Each one has a value, a place that value came from, and a scope. The configuration file sets the server's default. `alter database` and `alter role` override it for one database or one role. `set` changes it for your session, and `set local` for one transaction, after which it snaps back.
You'll use the narrow scopes most. A report that needs more memory for one big sort should `set local work_mem` inside its transaction, not raise it for every connection on the server. `show work_mem` reads the current value, and `pg_settings` tells you where it came from ([The settings that matter](/en/30-configuration/#basics-chapter-30)).
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('work_mem defaults to 4MB',
> current_setting('work_mem') = '4MB');
> begin;
> set local work_mem = '64MB';
> select lab.prove('set local changes it for this transaction only',
> current_setting('work_mem') = '64MB');
> commit;
> select lab.prove('and it''s back at commit',
> current_setting('work_mem') = '4MB');
> select lab.prove('pg_settings says where each value came from',
> (select source from pg_settings where name = 'work_mem') = 'default');
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## Extensions arrive with one command
An **extension** adds types, functions, operators, or index methods to one database with `create extension`. Some ship with Postgres (the "contrib" modules); others you install on the server first. The lab database has the five this book leans on: `pg_stat_statements` to rank queries, `pageinspect` to read raw pages, `pgstattuple` and `pg_buffercache` to measure tables and the cache, and `pg_trgm` for text search.
Managed services allow a fixed list, so check it before you design around one ([Extensions worth knowing](/en/16-extensions/#basics-chapter-16)).
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('the lab database has the book''s five extensions installed',
> (select count(*) from pg_extension
> where extname in ('pg_stat_statements', 'pg_trgm', 'pageinspect', 'pg_buffercache', 'pgstattuple')) = 5);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## Your data is files you never touch
Under it all, every table and index is a file in the server's data directory, named by numbers, not by your table names:
```text
file | bytes
------------------+-----------
base/16841/16644 | 288137216
```
288,137,216 bytes is 35,173 pages of 8,192 bytes, the same count the catalog gave. Postgres reads and writes those files a page at a time, and that's where the rest of the book begins. [Everything is a page](/en/04-storage/#basics-chapter-4) opens one up.
Never edit, copy, or delete anything in the data directory by hand, least of all `pg_wal`. The server is the only thing that understands those files, and a copy taken from under a running server is not a backup.
> [!EXAMPLE]- Prove it · lab `01-basics`
>
> ```sql
> select lab.prove('events is a file under base/ of exactly 35,173 pages of 8,192 bytes',
> pg_relation_filepath('events') like 'base/%'
> and pg_relation_size('events') = 35173 * 8192);
> ```
>
> [Full lab script](https://www.flagon.io/books/eight-kilobytes/lab/01-basics.sql)
## A handful of psql commands cover this book
Every example in the book ran in `psql`, the command-line client that ships with Postgres. GUI clients work fine, but a handful of backslash commands are worth knowing by heart:
| Command | Does |
| --- | --- |
| `\d name` | describes a table: columns, indexes, constraints |
| `\dt`, `\di`, `\dn`, `\du` | lists tables, indexes, schemas, roles |
| `\x` | prints wide rows vertically, one column per line |
| `\timing` | prints each statement's time |
| `\e` | opens the last query in your editor |
**Table 2-1.** A handful of psql commands cover this book
Add `\?` for the rest. When a backslash command shows you something useful, `\set ECHO_HIDDEN on` prints the catalog query behind it, which is the fastest way to learn the catalog.
## The short version
- A table is rows that share typed columns. The primary key finds a row; a foreign key points at one in another table.
- `select` reads and changes nothing. In Postgres an `update` writes a new copy of the row, and a `delete` leaves the old row in place, until vacuum clears them.
- An index turned 1,126 pages into 4 for one lookup, and every write pays to keep it current.
- One server holds many databases that can't query each other; inside one, schemas are folders and `search_path` picks among them. Roles are shared by the whole server, and apps should connect as one that owns nothing.
- Every connection is a process with its own memory, which is why connections cost what they do.
- Every statement runs in a transaction. Schema changes roll back too, and an open transaction holds what it touched.
- The catalog is queryable tables, settings have scopes (use the narrowest), and tables are files of 8 KB pages you never touch by hand.
## Further reading
- [The SQL Language](https://www.postgresql.org/docs/18/tutorial-sql.html), PostgreSQL documentation. The manual's own tutorial: tables, queries, joins, and updates, one short page each.
- [Architectural Fundamentals](https://www.postgresql.org/docs/18/tutorial-arch.html), PostgreSQL documentation. The two-page version of the process model, from the tutorial.
- [Schemas](https://www.postgresql.org/docs/18/ddl-schemas.html), PostgreSQL documentation. Schemas, `search_path`, and the usage patterns the manual recommends.
- [Database Roles](https://www.postgresql.org/docs/18/user-manag.html), PostgreSQL documentation. Roles, attributes, and membership.
- [System Catalogs](https://www.postgresql.org/docs/18/catalogs.html), PostgreSQL documentation. Every catalog table, column by column, for when `\d` isn't enough.
- [psql](https://www.postgresql.org/docs/18/app-psql.html), PostgreSQL documentation. Every backslash command and variable.