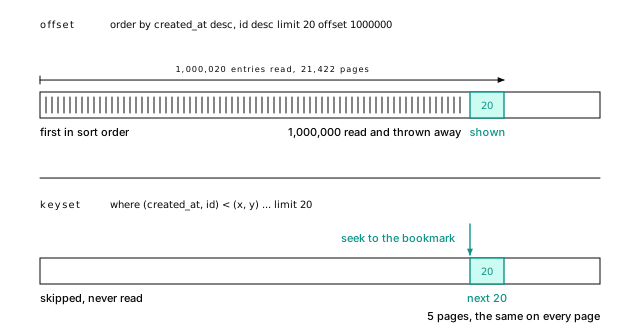
selectlab.prove('OFFSET 100,000 reads about 2,146 pages',lab.buffers($$selectid,kind,created_atfromeventsorderbycreated_atdesc,iddesclimit20offset100000$$)between1800and2500);selectlab.prove('OFFSET 1,000,000 reads about 21,422 pages, ten times OFFSET 100,000: linear in depth',lab.buffers($$selectid,kind,created_atfromeventsorderbycreated_atdesc,iddesclimit20offset1000000$$)between19000and24000);selectlab.prove('OFFSET 1,000,000 walks 1,000,020 index entries to return 20',(select(lab.find_node(p->'Plan','Index Scan')->>'Actual Rows')::numeric=1000020fromlab.plan($$selectid,kind,created_atfromeventsorderbycreated_atdesc,iddesclimit20offset1000000$$)p));
像 created_at desc, id asc 这样的混合方向需要按这种方式声明索引,而且不能使用行比较。
动手验证 · lab 21-queries
-- the last row of the page before OFFSET 1000000 is the cursor
selectcreated_atascur_ts,idascur_idfromeventsorderbycreated_atdesc,iddescoffset999999limit1\gsetselectlab.prove('keyset returns exactly the page OFFSET 1,000,000 returns',(selectarray_agg(idorderbycreated_atdesc,iddesc)from(selectid,created_atfromeventswhere(created_at,id)<(:'cur_ts'::timestamptz,:'cur_id'::bigint)orderbycreated_atdesc,iddesclimit20)k)=(selectarray_agg(idorderbycreated_atdesc,iddesc)from(selectid,created_atfromeventsorderbycreated_atdesc,iddesclimit20offset1000000)o));selectlab.prove('keyset reads under 10 pages at the same depth',lab.buffers(format($$selectid,kind,created_atfromeventswhere(created_at,id)<(%L::timestamptz,%s)orderbycreated_atdesc,iddesclimit20$$,:'cur_ts',:'cur_id'))<10);
如果 NOT IN 下的子查询产生一个 NULL,查询会悄悄返回零行(一个 NULL 就会让 NOT IN 什么也不返回)。同一个 NULL 规则也会阻止 Postgres 把它变成反连接,因此一旦子查询结果超过work_mem,它就会为每个外侧行重新扫描。“没有事件的用户”如果写成 not in (select user_id from events),代价会接近 39 亿,因为这可能意味着 1600 亿次比较(80,000 个没有事件的用户,每个都要与 200 万个 user_id 比较)。写成 not exists 后,它是一个 Hash Right Anti Join,每张表各扫描一次,代价为 68,394。
永远不要使用带子查询的 NOT IN
始终写 NOT EXISTS。只有由不含 NULL 的常量组成的短列表才可以使用 NOT IN(status not in ('done', 'failed'))。
 Aggregate  (cost=3899296376.00..3899296376.01 rows=1 width=8)
   ->  Seq Scan on users u  ...
         Filter: (NOT (ANY (id = (SubPlan 1).col1)))
         SubPlan 1
           ->  Materialize  (cost=0.00..72985.90 rows=1999993 width=8)

 Aggregate  (cost=68394.12..68394.13 rows=1 width=8)
   ->  Hash Right Anti Join  (cost=3376.00..68193.50 rows=80249 width=0)
Filter 中写的是 SubPlan,而不是 hashed SubPlan:两百万个 user_id 放不进 work_mem,所以 80,000 个没有事件的用户中的每一个都会扫描全部这些值。对于 projects.owner_id(20,000 行),它会得到 hashed SubPlan 1,并在 12 ms 内完成;这就是 NOT IN 能通过评审、却会在生产环境失败的原因。
动手验证 · lab 21-queries
selectlab.prove('NOT IN over 2 million events is a plain subplan costed in the billions',(select(p->>'Total Cost')::numeric>1e9andlab.find_node(p,'Seq Scan')->>'Filter'notlike'%hashed%'fromlab.estimate($$selectcount(*)fromusersuwhereu.idnotin(selectuser_idfromevents)$$)p));selectlab.prove('NOT EXISTS over the same tables is an anti-join costed under 100,000',(select(p->>'Total Cost')::numeric<100000and(lab.join_types($$selectcount(*)fromusersuwherenotexists(select1fromeventsewheree.user_id=u.id)$$))[1]like'%Anti'fromlab.estimate($$selectcount(*)fromusersuwherenotexists(select1fromeventsewheree.user_id=u.id)$$)p));
对 date_trunc、extract 和算术表达式也是一样:created_at + interval '1 day' > now() 读取了全部 35,173 个页;created_at > now() - interval '1 day' 使用索引。如果确实需要对列应用函数,就为表达式建立索引(索引会准确存储你提供的表达式)。这要求表达式是 IMMUTABLE 的,而 created_at::date 作用于 timestamptz 时并不满足这一要求:它取决于会话时区,因此 create index ... ((created_at::date)) 会被拒绝。请对 ((created_at at time zone 'UTC')::date) 建立索引,并用相同的表达式查询。
动手验证 · lab 21-queries
-- :'day0' is '2026-09-01' (set at the top of the lab)
selectlab.prove('created_at::date = a day reads every page of the table',lab.buffers(format($$selectcount(*)fromeventswherecreated_at::date=%L::date$$,:'day0'))>=35173);selectlab.prove('the half-open range on the bare column reads under 50 pages',lab.buffers(format($$selectcount(*)fromeventswherecreated_at>=%Landcreated_at<%L::timestamptz+interval'1 day'$$,:'day0',:'day0'))<50);
selectlab.prove('where id = 42 is an index scan that reads under 10 pages','Index Scan'=any(lab.nodes('select * from events where id = 42'))andlab.buffers('select * from events where id = 42')<10);selectlab.prove('where id = 42.0 casts the column to numeric and reads the whole table (over 35,000 pages)',lab.estimate('select * from events where id = 42.0')->>'Filter'='((id)::numeric = 42.0)'andlab.buffers('select * from events where id = 42.0')>35000);
同样返回那一行,访问 10 个缓冲区即可,而不是 1,317 个。当两个分支不可能重叠时,使用 union all,跳过排序。
深入阅读:读取 UNION 计划
 Unique (actual time=0.059..0.061 rows=1.00 loops=1)
   Buffers: shared hit=4 read=6
   ->  Sort ...
         ->  Append ... rows=2.00 ...
               ->  Index Scan using projects_name_idx on projects p ...
               ->  Nested Loop ...
                     ->  Index Scan using users_email_idx on users u ...
                     ->  Index Scan using projects_owner_id_idx on projects p_1 ...
selectlab.prove('an OR across the join scans both tables: over 1,000 pages for one row',(select(p->'Plan'->>'Actual Rows')::numeric=1and(p->'Plan'->>'Shared Hit Blocks')::int+(p->'Plan'->>'Shared Read Blocks')::int>1000fromlab.plan($$selectp.id,p.namefromprojectspjoinusersuonu.id=p.owner_idwherep.name='Project 4242'oru.email='user29695@example.com'$$)p));selectlab.prove('the UNION of two indexed queries reads under 30 pages for the same row',(select(p->'Plan'->>'Actual Rows')::numeric=1and(p->'Plan'->>'Shared Hit Blocks')::int+(p->'Plan'->>'Shared Read Blocks')::int<30fromlab.plan($$selectp.id,p.namefromprojectspwherep.name='Project 4242'unionselectp.id,p.namefromprojectspjoinusersuonu.id=p.owner_idwhereu.email='user29695@example.com'$$)p));
 CTE Scan on recent (actual time=0.931..9.274 rows=3.00 loops=1)
   Filter: (project_id = 4242)
   Rows Removed by Filter: 38354
   Storage: Disk  Maximum Storage: 4672kB
   Buffers: shared hit=602 read=224, temp written=584
这一周的全部 38,357 行都被取出,Storage: Disk 说明数据量超过了 work_mem 限制,已溢写到磁盘。内联后,它变成一个 Index Scan,其中的 Index Cond 同时带有两个条件。
动手验证 · lab 21-queries
-- :'last_week' is '2026-09-29' (set at the top of the lab)
selectlab.prove('a CTE referenced once is inlined: one index scan, under 20 pages',(selectp->'Plan'->>'Node Type'='Index Scan'and(p->'Plan'->>'Shared Hit Blocks')::int+(p->'Plan'->>'Shared Read Blocks')::int<20fromlab.plan(format($$withrecentas(select*fromeventswherecreated_at>%L)selectid,kindfromrecentwhereproject_id=4242$$,:'last_week'))p));selectlab.prove('MATERIALIZED fetches the whole week first: a CTE Scan, hundreds of pages, and a temp file',(selectp->'Plan'->>'Node Type'='CTE Scan'and(p->'Plan'->>'Shared Hit Blocks')::int+(p->'Plan'->>'Shared Read Blocks')::int>500and(p->'Plan'->>'Temp Written Blocks')::int>0fromlab.plan(format($$withrecentasmaterialized(select*fromeventswherecreated_at>%L)selectid,kindfromrecentwhereproject_id=4242$$,:'last_week'))p));
第一次请求返回 id 1;重试返回零行,意思是“已经完成”:查找原来的记录并返回相同答案。这个键在每个租户内唯一,unique (account_id, idempotency_key)。
深入阅读:用 Go 实现幂等,以及在一条语句中取回 ID
在 Go 中使用 pgx:
varidint64err:=tx.QueryRow(ctx,`
insert into payments (account_id, idempotency_key, amount_cents)
values ($1, $2, $3)
on conflict (account_id, idempotency_key) do nothing
returning id`,acct,key,cents).Scan(&id)iferrors.Is(err,pgx.ErrNoRows){// A previous request with this key won. Return its result.err=tx.QueryRow(ctx,`
select id from payments
where account_id = $1 and idempotency_key = $2`,acct,key).Scan(&id)}
如果两个相同的请求在同一时刻到达,第二次插入会等待第一个事务;第一个事务提交后,第二次插入什么也不做;在读已提交隔离级别下,后续的 select 会看到已提交的行。若要在一条语句中取回 ID,do update set idempotency_key = excluded.idempotency_key returning id, old.id is null as inserted 可以做到(重试时返回 1 | f),代价是每次重试都会产生一个新的行版本。
动手验证 · lab 21-queries
selectlab.prove('the retry with the same key inserts nothing and returns no rows',(selectcount(*)fromids)=0and(selectcount(*)frompayments)=1);
两个 dblink 会话对同一个新键执行同一条语句,第一个会话处于打开的事务中。使用 ON CONFLICT 时,第二个会话会等待第一个会话的锁(wait_event_type = 'Lock');第一个提交后,它会更新新行:没有错误,计数为 2。
动手验证 · lab 21-queries
selectdblink_exec('a','begin')\g/dev/nullselectdblink_exec('a',$$insertintoproject_daily_countsvalues(1,'2026-01-01','x',1)onconflict(project_id,day,kind)doupdatesetn=project_daily_counts.n+excluded.n$$)\g/dev/nullselectdblink_send_query('b',$$insertintoproject_daily_countsvalues(1,'2026-01-01','x',1)onconflict(project_id,day,kind)doupdatesetn=project_daily_counts.n+excluded.n$$)\g/dev/nullselectpg_sleep(0.3)\g/dev/nullselectlab.prove('a concurrent ON CONFLICT on the same key waits for the first transaction',(selectwait_event_type='Lock'frompg_stat_activitywhereapplication_name='upsert-b'));selectdblink_exec('a','commit')\g/dev/nullselectlab.finish('b')asb_result\gsetselectlab.prove('then it updates instead of failing: no error, n = 2',:'b_result'='ok'and(selectnfromproject_daily_countswhereproject_id=1andkind='x')=2);
使用 MERGE 时,两个会话都会判断键不存在。第一个提交后,第二个会话的插入会失败,并报告 duplicate key value violates unique constraint;应用会看到一个必须重试的错误。
动手验证 · lab 21-queries
-- session a has run this MERGE in an open transaction; session b runs it too
selectdblink_send_query('b',$$mergeintoproject_daily_countstusing(values(2::bigint,date'2026-01-01','x',1::bigint))s(p,d,k,n)ont.project_id=s.pandt.day=s.dandt.kind=s.kwhenmatchedthenupdatesetn=t.n+s.nwhennotmatchedtheninsertvalues(s.p,s.d,s.k,s.n)$$)\g/dev/nullselectpg_sleep(0.3)\g/dev/nullselectdblink_exec('a','commit')\g/dev/nullselectlab.finish('b')asb_result\gsetselectlab.prove('two concurrent MERGEs both decide the key is missing, and the second fails with a unique violation',:'b_result'like'%duplicate key value violates unique constraint%');
这种模式需要一个以分组键开头、再接排序键的索引。没有它,每次 LATERAL 运行都要扫描并排序,结果比窗口函数版本更糟。如果即使没有事件也应显示项目,就使用 left join lateral (...) on true。在 311 个页中,有 191 个用于扫描 projects;这张表在 account_id 上没有索引。
窗口函数版本有一个 Run Condition(PostgreSQL 15+),会在每个分区中提前停止编号,但行仍然会被取出并排序。如果每组恰好只需要一行,select distinct on (project_id) ... order by project_id, created_at desc 简洁有效,前提是大多数分组本来就会被读取。
窗口函数适合时,还有两个问题会咬你。在有 order by 且没有显式指定窗框时,默认窗框是 range between unbounded preceding and current row,它会包含所有与当前行并列的行,因此累加和会一次增加整个并列组的值;如果你想逐行计算,就写 rows。此外,按日 group by 生成的图表会跳过没有行的日期,于是 lag() 比较的是错误的日期:用 generate_series 生成桶,再把数据左连接到这些桶上。
动手验证 · lab 21-queries
selectlab.prove('row_number() fetches every event of every project: about 2,084 rows and over 1,500 pages for 60 results',(select(p->'Plan'->>'Actual Rows')::numeric=60and(lab.find_node(p->'Plan','Sort')->>'Actual Rows')::numericbetween2000and2200and(p->'Plan'->>'Shared Hit Blocks')::int+(p->'Plan'->>'Shared Read Blocks')::int>1500fromlab.plan($$select*from(selectp.idaspid,p.name,e.id,e.kind,e.created_at,row_number()over(partitionbye.project_idorderbye.created_atdesc)asrnfromprojectspjoineventseone.project_id=p.idwherep.account_id=42)twherern<=3$$)p));selectlab.prove('LATERAL with LIMIT 3 runs 20 short index scans: the same 60 rows in about 311 pages',(select(p->'Plan'->>'Actual Rows')::numeric=60and(lab.find_node(p->'Plan','Limit')->>'Actual Loops')::int=20and(p->'Plan'->>'Shared Hit Blocks')::int+(p->'Plan'->>'Shared Read Blocks')::int<400fromlab.plan($$selectp.id,p.name,e.id,e.kind,e.created_atfromprojectspcrossjoinlateral(selectid,kind,created_atfromeventswhereproject_id=p.idorderbycreated_atdesclimit3)ewherep.account_id=42$$)p));